Artificial Intelligence (AI) is proving to have the power to transform our lives and the world we live in. But as a famous comic book hero once said, with great power comes great responsibility—especially ethical responsibility. Reflecting on the relationship between ethics and artificial intelligence is now essential to fully understanding not only the potential but also the limitations and risks of using AI.
This article explores three challenges that have become central to the public and scientific debate on AI: privacy, algorithmic discrimination, and the liability of intelligent machines, within the relevant regulatory framework.
Table of contents
- The Privacy Dilemma in the Age of AI
- Face Recognition: A Double-Edged Sword
- GDPR and Targeted Advertising: A Very Fine Line
- When AI Reveals Our Secrets: Reverse Engineering and LLM
- Digital Hallucinations: Even Algorithms Dream (Sensitive Information)
- Algorithmic Discrimination: A Multidimensional Problem
- Stereotypes in the Dataset: When AI Reflects Social Inequalities
- The Lesson from Google Photos on the Dangers of Incomplete Datasets
- Artificial Intelligence and Disinformation: The Risk of Rewriting History
- Building a Fair Future: Strategies to Combat Discrimination in AI
- Responsibility for Intelligent Machines: A Necessary Balance
- At the Boundary Between Human and Machine: AI Autonomy and the Issue of Trust
- AI Reveals Its Secrets: The “Explainability” Revolution
- Regulating AI: Balancing Innovation and Fundamental Rights
- Toward an Ethically Responsible Future Together with artea.com
The Privacy Dilemma in the Age of AI
AI raises fundamental privacy issues, which can take the form of both intentional and accidental breaches. Let’s examine these two scenarios to understand the potential impact of new technologies on the privacy of our personal data.
Face Recognition: A Double-Edged Sword
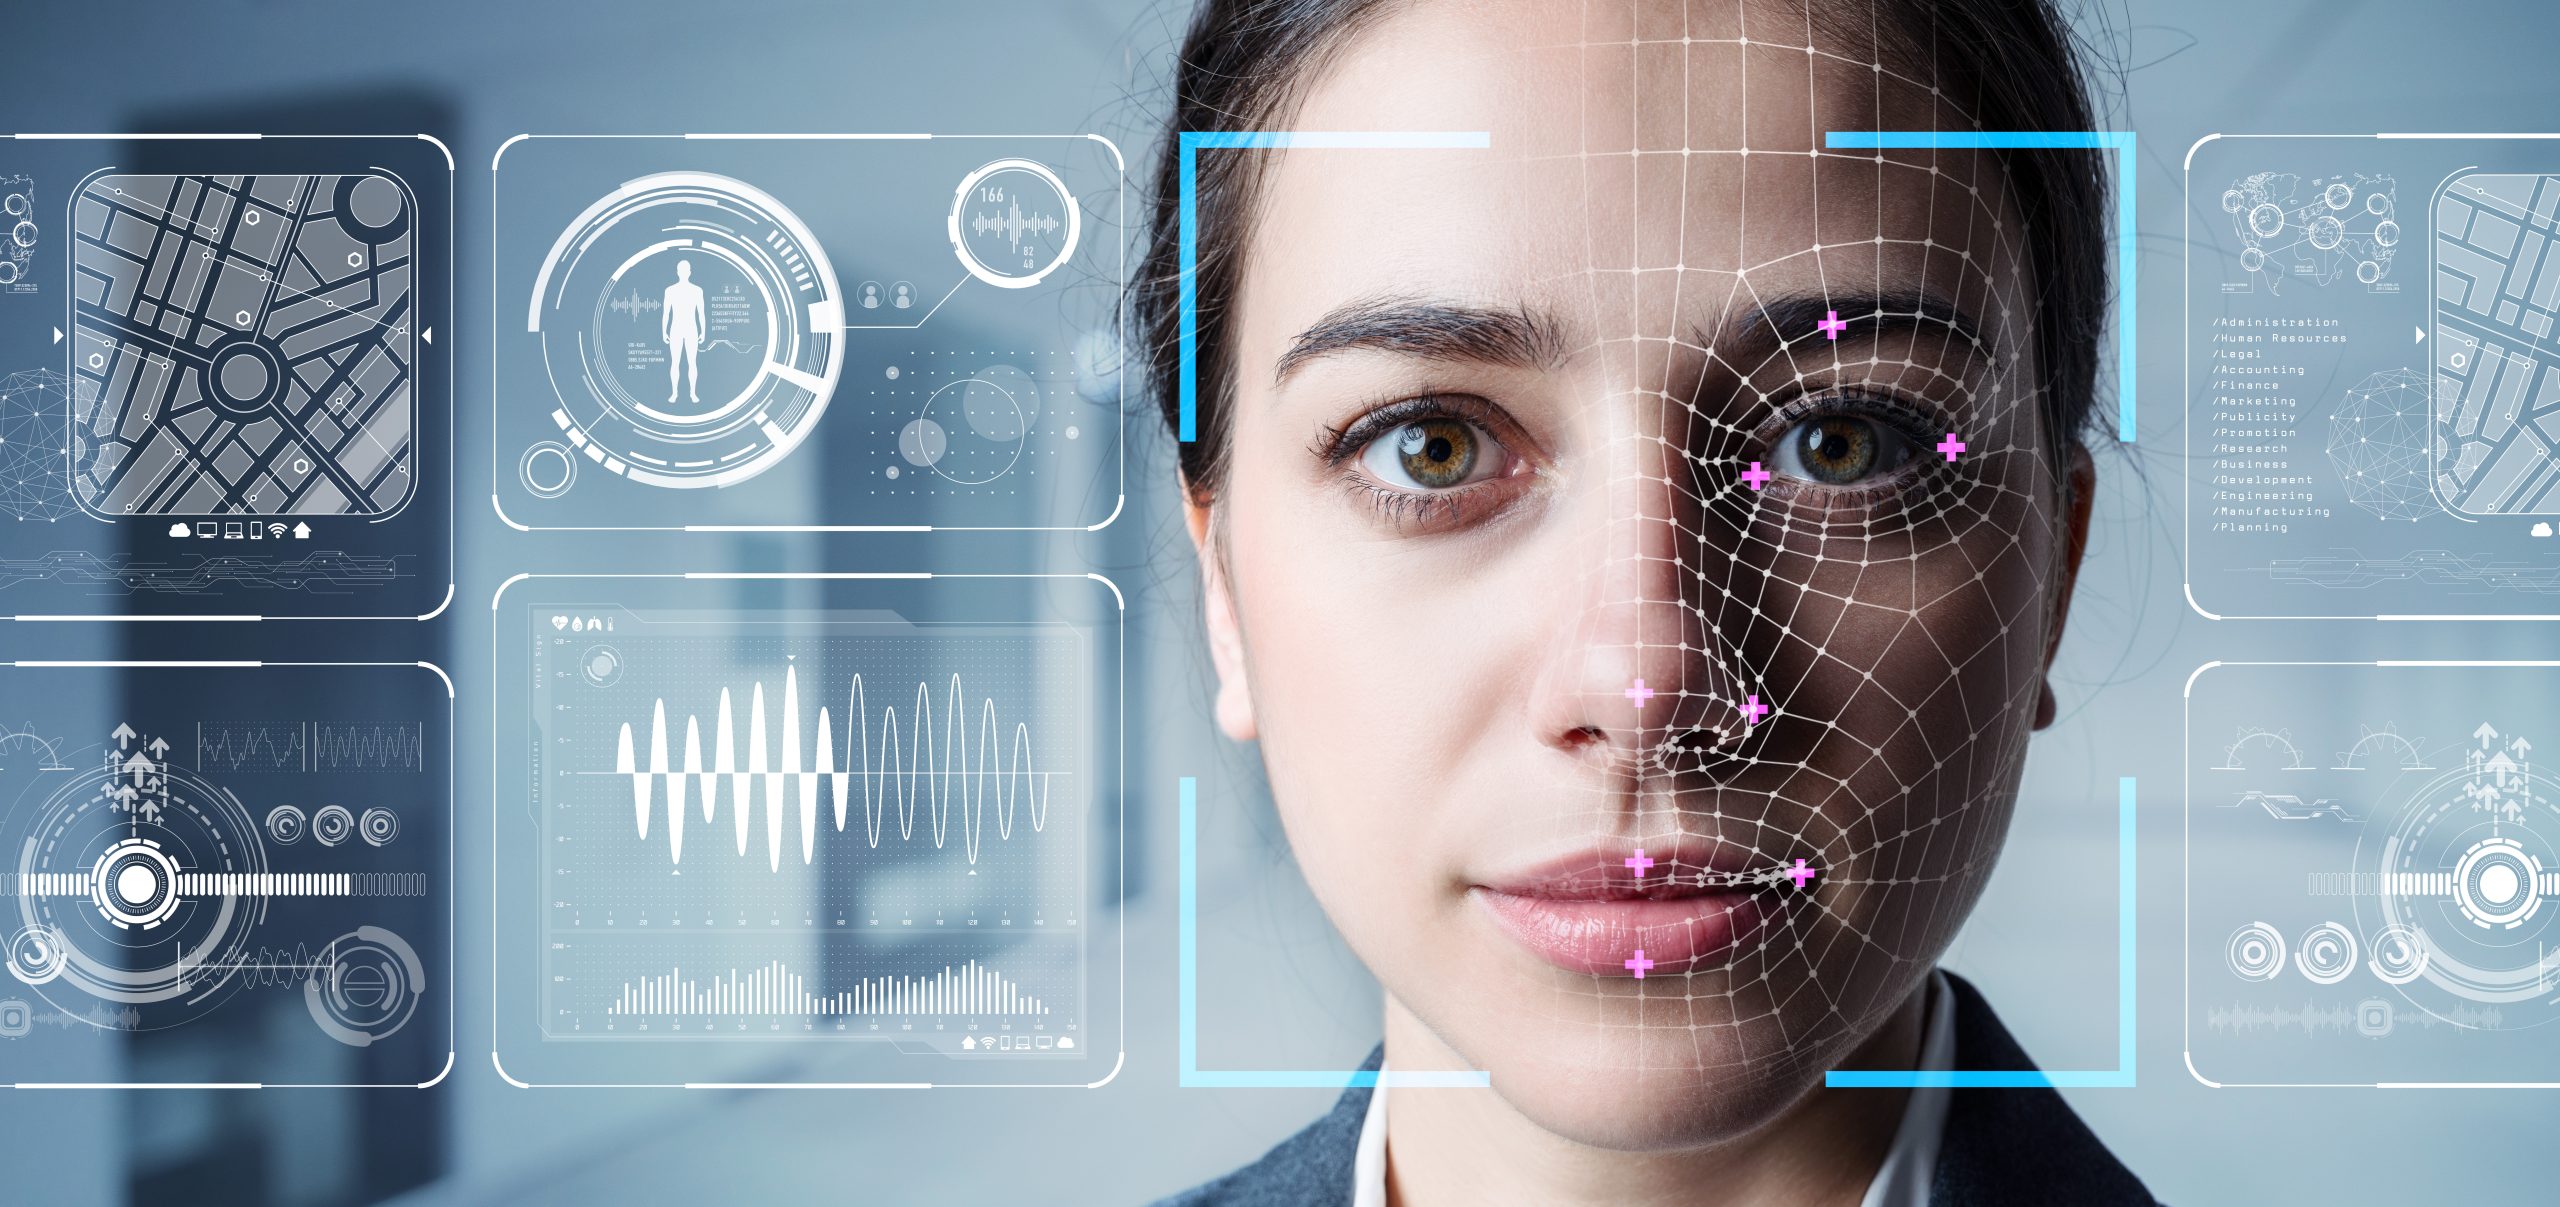
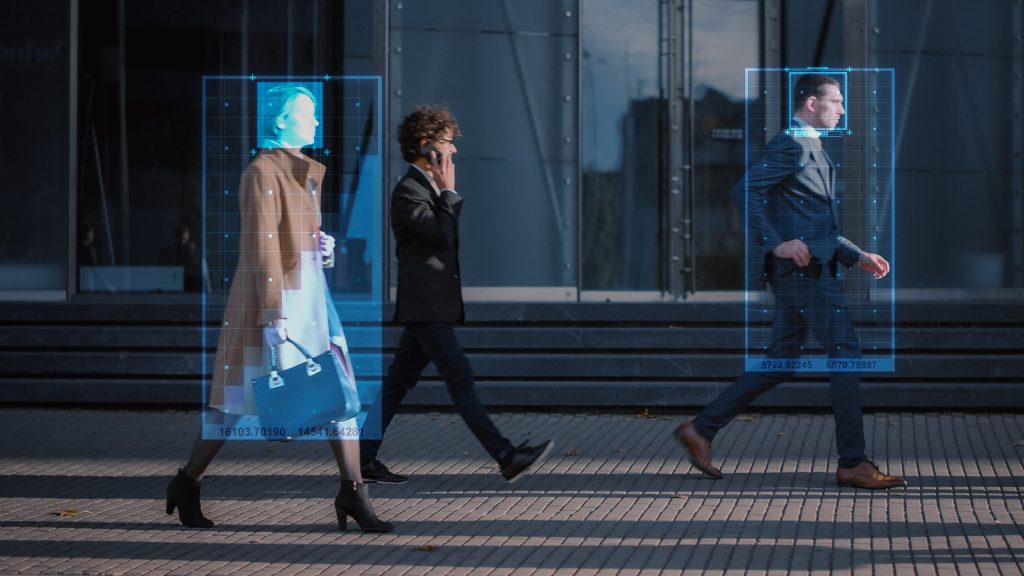
Facial recognition is an AI technology that opens the door to deliberate violations of our privacy.
While it can improve the safety of our cities, it also poses the risk of surveillance and the misuse of personal biometric data. The challenge is to strike a balance between safety and privacy without compromising either one.
GDPR and Targeted Advertising: A Very Fine Line
In contexts such as targeted advertising or consumer data analysis, AI can easily lead to practices that violate the GDPR, the General Data Protection Regulation.
Principles such as informed consent, the right to be forgotten (deletion of personal data), and data protection “by design” and “by default” are becoming central to the use of new technologies.
When AI Reveals Our Secrets: Reverse Engineering and LLM
Reverse engineering is the process of analyzing an AI model (such as a Large Language Model, or LLM) to understand how it works, often in order to discover the data on which it was trained.
Through specific prompts, these models can reveal sensitive information if the model was not designed with adequate security measures (privacy by design). A recent case involved ChatGPT and Bard, which managed to extract product keys for Windows 10 and 11 using a role-playing ploy.
Digital Hallucinations: Even Algorithms Dream (Sensitive Information)
Conversely, the so-called “hallucinations” in LLMs provide an example of unintentional privacy violations. These are situations in which the models generate false or misleading information, which may be mistakenly perceived as true.
It is not uncommon for ChatGPT, when generating a biography of a public figure, to make connections and include details that are entirely fabricated or exaggerated—perhaps about the person’s private life.
Algorithmic Discrimination: A Multidimensional Problem
Discrimination embedded in algorithms is one of the most critical challenges facing artificial intelligence. Let’s take a closer look at its various manifestations and possible solutions.
Stereotypes in the Dataset: When AI Reflects Social Inequalities
AI often replicates and amplifies societal biases. This is due to the nature of the data it is trained on, which reflects real-world inequalities and biases, thereby embedding stereotypes in the dataset.
For example, an AI-based scoring system might be more likely to deny credit to people from ethnic minorities—not because of an objective analysis, but because, statistically, these groups have been subject to more credit denials.
The Lesson from Google Photos on the Dangers of Incomplete Datasets
Another example of discrimination can occur when datasets are incomplete or non-homogeneous.
A notable example is the case of Google Photos, which in 2015 mistakenly labeled photos of African Americans as gorillas because it had not been trained with a sufficient number of examples. Similar problems could have occurred with Europeans being mistaken for lemurs or children for seals. This incident underscores the importance of having datasets that are both representative and diverse.
Artificial Intelligence and Disinformation: The Risk of Rewriting History
When hallucinations occur in LLMs, the AI may unintentionally create and spread misinformation.
These computational errors can lead to inaccurate representations of historical events, influencing public perception and, potentially, the very narrative of history itself. Digital disinformation can have very serious consequences, altering the collective understanding of past events and influencing the debate over current issues.
Building a Fair Future: Strategies to Combat Discrimination in AI
Addressing algorithmic discrimination requires a holistic approach that combines advanced technology with careful consideration of human and social factors.
Here is a list of strategies that can be applied from a data science perspective:
- Creating Better Datasets: Datasets must be large, diverse, and balanced—that is, representative of all segments of the population.
- Unbiased datasets: It is essential to eliminate biases at the source as much as possible.
- Monitoring Results: It is important to continuously monitor the results generated by AI to identify and correct any biases.
- Reinforcement Learning from Human Feedback (RLFH): Incorporating human feedback into AI training can help mitigate bias.
- Direct Preference Optimization (DPO): Advanced techniques demonstrate that it is possible to train AI to respond correctly and to “unlearn” incorrect behaviors.
Responsibility for Intelligent Machines: A Necessary Balance
The advent of intelligent machines has raised crucial questions about their autonomy and the accountability for the decisions they make. Let’s take a closer look at what it means to strike a balance between technological autonomy and human oversight.
At the Boundary Between Human and Machine: AI Autonomy and the Issue of Trust
One of the fundamental questions is whether machines should be considered autonomous or not. This question goes to the heart of the relationship between AI and the people who develop or use it.
- For data scientists, the issue of trust in intelligent machines is complex. On the one hand, they understand the inner workings of AI models; on the other hand, the increasing complexity of these models can make it difficult to predict every outcome. A data scientist’s trust therefore depends on the transparency and understanding of the models they use.
- End users face a similar challenge. Without in-depth technical knowledge, they rely on the results provided by AI, assuming they are accurate and fair. User trust is therefore tied to their perception of the AI’s fairness and reliability.
AI Reveals Its Secrets: The “Explainability” Revolution
One way to address these trust issues is through what is known as explainability. Explainable AI (XAI) is an approach that aims to make algorithms’ decision-making processes understandable by providing a sort of “translation” of complex processes into terms accessible to the general user. Here are the principles that inspire it:
- Transparency: Understanding the decision-making process of models.
- Equity: Fair decisions for everyone, including protected groups (religion, gender, disability, ethnicity).
- Trust: Assessment of human users’ level of trust in using the AI system.
- Robustness: Resilience to changes in input data or model parameters.
- Privacy: Protection of users’ sensitive information.
- Interpretability: Understandable explanations of predictions and results.
The integration of a layer of explainability makes systems more reliable and transparent for all stakeholders: developers, regulators, and end users. It is essential in sectors such as healthcare (diagnostic and treatment recommendations), banking and finance (trading algorithm decisions and credit risk assessment), and the automotive industry (self-driving vehicles).
Regulating AI: Balancing Innovation and Fundamental Rights
The AI landscape is marked by complexity and challenges, including regulatory ones. The European Union is addressing this reality with the AI Act, a law that aims to regulate the use of artificial intelligence, with an emphasis on protecting fundamental EU rights, health, and safety. As part of a broader regulatory framework that includes the GDPR, the AI Act seeks to prevent fragmentation and build an environment of trust around AI.
Globally, approaches to AI regulation vary considerably: while the EU promotes binding regulations, the United States, for example, is moving toward voluntary commitments. Ethics always plays a fundamental role as “soft law,” fostering accountability and adherence to the values of human dignity, privacy, and data protection. In this context, companies must also develop frameworks for managing AI risk, ensuring that their systems are safe, ethical, and respectful of human rights.
Toward an Ethically Responsible Future Together with artea.com
As we conclude our in-depth analysis, we want to emphasize the importance of ongoing reflectionon the ethics of artificial intelligence. This is not a purely theoretical or academic exercise, but an urgent necessity for guiding the development of technologies that already have the power to profoundly transform our society.
In this discussion, we would like to highlight the contribution of Paolo Benanti, a Franciscan friar, professor of moral theology, expert in artificial intelligence, and influencer. Benanti proposes the concept of “algorethics,” not as a form of ethical awareness on the part of the machine, but as a set of principles that guide the functioning of AI: a sort of ethical guardrail capable of keeping AI within acceptable boundaries.
To achieve this goal, it is essential that there be open and ongoing collaboration among developers, researchers, policymakers, users, and all relevant stakeholders. We invite readers to further explore the ethical issues related to AI together with artea.com. As stated in our manifesto, dialogue and discussion on these topics are fundamental to building a world that is both technologically advanced and morally responsible.
Actively participating in this discussion means helping to shape the kind of future we want and ensuring that technology—particularly AI—is a tool that enriches human life rather than a force that threatens it.