The data age has presented companies with a crucial dilemma: How can they store an ever-increasing amount of information effectively and cost-efficiently?
Often, the volume of data exceeds the storage capacity of traditional solutions, such as relational databases. This is where the concept of a data lake comes into play. In this article, we will explore its structure, its distinctive features compared to other architectures, and its applications, which go far beyond mere data storage.
Table of contents
- Definition of a Data Lake
- The Dilemma of Data Archiving: An Overview of Typical Cases
- Future Needs and the Importance of Historical Data: A Hidden Treasure Trove
- The Power of Historical Data in an AI-Driven World
- From Healthcare to Safety: A Look Beyond
- A backup is worth more than a thousand words
- What should you do when there's too much data?
- What are the differences between a data lake and other storage systems?
- Anatomy of a Data Lake: Versatility
- Benefits of a Data Lake: Scalability and Costs
- Turn your data into renewable energy with artea.com: Your ideal partner for customized data lake solutions
Definition of a Data Lake
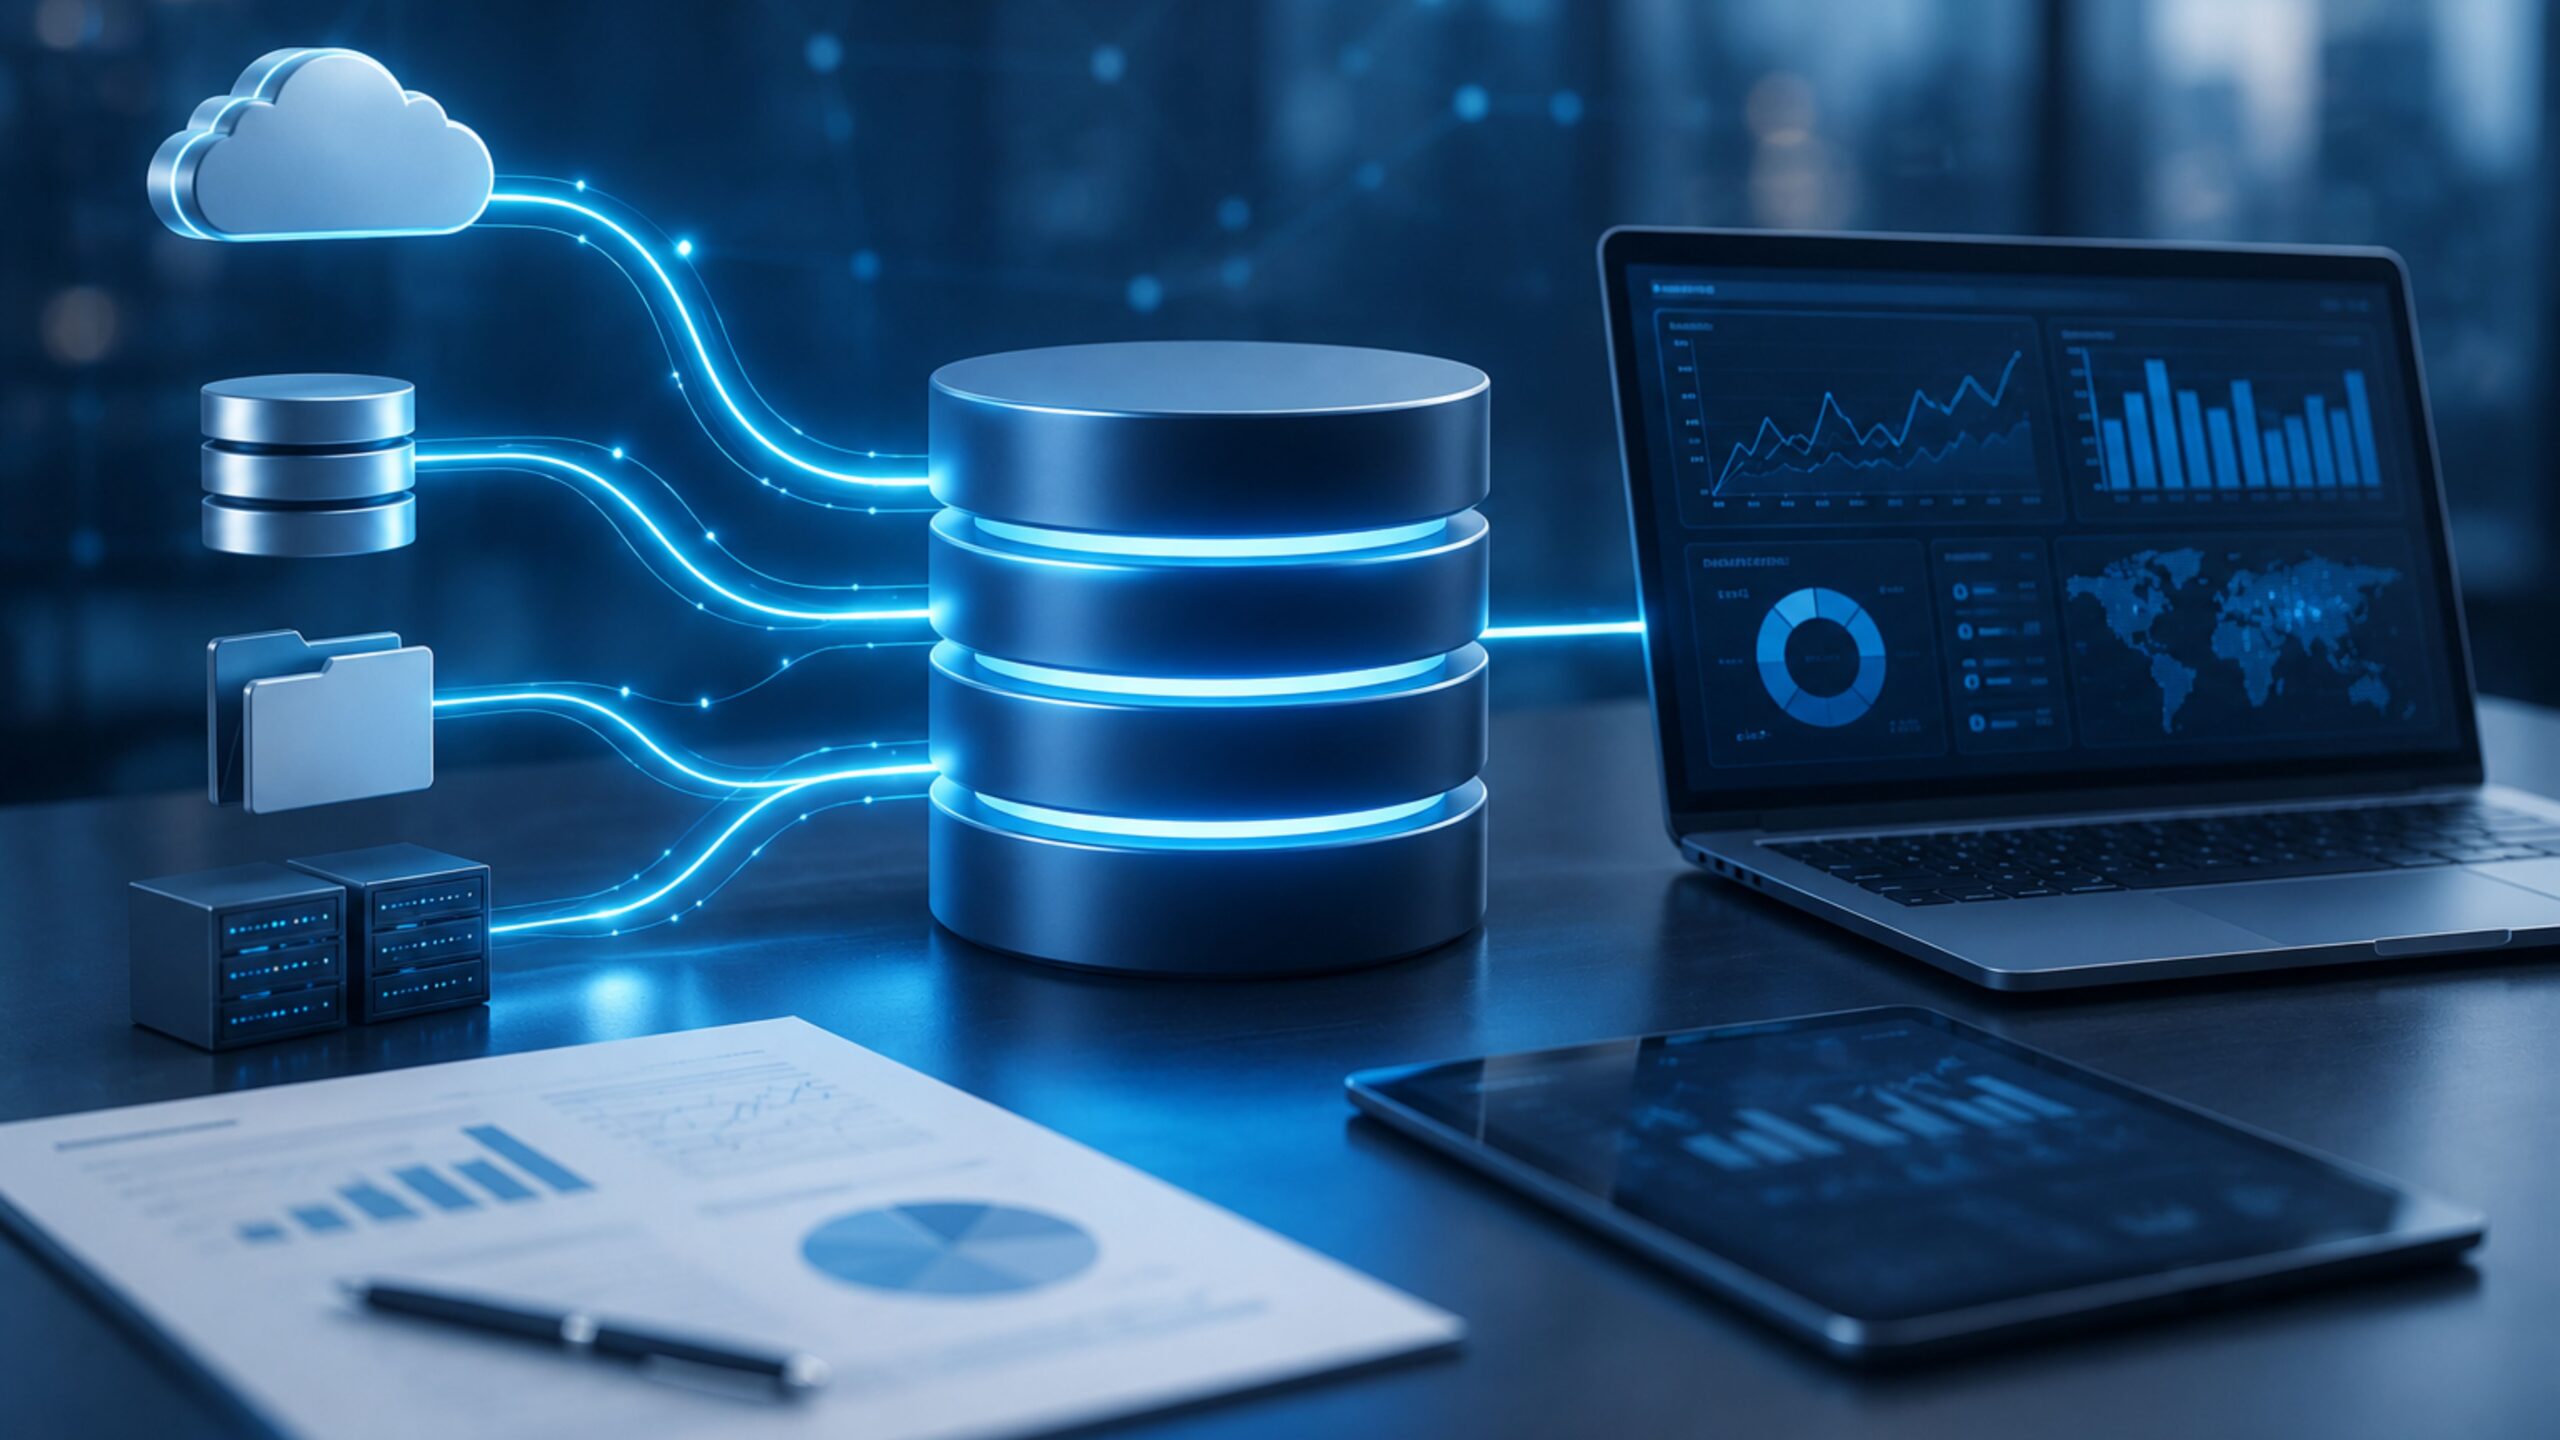
A data lake is a flexible and scalable storage environment that holds raw data. Think of it as a giant reservoir where data can flow in from various sources and remain in its unprocessed form until it is needed for some type of analysis or operation.
The Dilemma of Data Archiving: An Overview of Typical Cases
But let’s take it one step at a time: in what situations might managing a large volume of data require the use of a data lake?
- Accounting systems: Think of old-school accounting software. In these systems, data is stored for only a few years and then deleted to free up space. As a result, historical transactions risk being lost or trapped in backups that are difficult to restore for other purposes, compromising long-term analysis.
- Corporate communication: Consider how difficult it is to trace a chronological sequence of decisions if the oldest corporate emails have been deleted. Many organizations delete their oldest communications, thereby losing an extraordinary wealth of information about the company’s history.
- System logs: In the world of e-commerce, system logs serve as a kind of logbook that records events and activities, providing valuable insights into user behavior and website performance. However, over time, this data accumulates and is often deleted due to its sheer volume.
- Internet of Things (IoT): Sensors embedded in devices—such as connected cars or industrial systems—generate petabytes of data that are difficult to manage using traditional tools. In most cases, this data is used to achieve an immediate business objective and then discarded.
- Healthcare: In the medical field, high-resolution images—such as MRIs and CT scans—take up enormous amounts of storage space. They are typically saved on DVDs and given to the patient, so the clinic loses track of them permanently.
- Multi-source data: Today, every company receives data from diverse sources such as social media, geospatial data, temporary project data, documents, backups, database snapshots, and legacy systems. Without a proper storage system, it is impossible to manage this complexity.
Future Needs and the Importance of Historical Data: A Hidden Treasure Trove
“I deleted that data, and now I need it!” How many times have you heard something like that, perhaps from a coworker or a client?
We know—data can seem like a burden, like those old items crammed into the basement that we think we’ll never use again. But in a world where artificial intelligence and machine learning are no longer the stuff of science fiction, historical data becomes invaluable. Why? Let’s find out together.
The Power of Historical Data in an AI-Driven World
Let’s think for a moment about the retail sector. In an increasingly competitive market, predicting consumer trends becomes essential to gaining an edge over the competition. And that’s where we come in—or rather, that’s where historical data comes into play.
Thanks to sophisticated machine learning techniques, it’s possible to analyze historical data on customer purchases and predict which products will be in highest demand next season. If you think that’s amazing, how about this: some companies are already using historical data to personalize their offers and services, resulting in increased sales and customer satisfaction.
Imagine being able to say, “We know what you’ll want to buy before you even know it yourself!”
From Healthcare to Safety: A Look Beyond
It’s not just the business world that benefits from historical data. Let’s return to the field of healthcare and look at an example.
Hospitals and clinics are adopting artificial intelligence systems to improve diagnostic protocols. How? By analyzing massive sets of historical data—from blood test results to medical imaging data—machine learning models can identify patterns and correlations that even the most experienced eyes might miss. The result? More accurate and timely diagnoses, which can mean the difference between life and death.
A backup is worth more than a thousand words
If you’re still not convinced, think of all the times a data backup could have saved the day.
Do you remember the famous ransomware attack that hit many companies a few years ago? Organizations that had backups of their historical data were able to resume operations in record time, minimizing financial losses and reputational damage.
What should you do when there's too much data?
In conclusion, historical data is not a burden to be preserved solely out of nostalgia, but a true hidden treasure—a valuable asset that can help organizations successfully navigate the complicated waters of the digital age.
However, when the sheer volume of historical data becomes an unsustainable problem, the solution is called a data lake.
What are the differences between a data lake and other storage systems?
While a relational database is like a cabinet with all the drawers labeled, a data lake is more like a warehouse: there’s no need to define in advance what will be stored and how.
This offers a higher degree of flexibility and allows you to manage structured, semi-structured, and unstructured data. Let’s take a look at what this entails below.
Anatomy of a Data Lake: Versatility
The main feature of a data lake is its versatility: these repositories can accommodate any type of data, from Excel spreadsheets (structured data) to tweets (semi-structured data) to YouTube videos (unstructured data). In summary:
- Structured data: This data is similar to the data contained in relational databases and has a well-defined structure, often in tabular form, that is easy to analyze.
- Semi-structured data: These are text files, such as system logs and JSON files, that do not follow a rigid structure; they are often organized in a tree-like hierarchy, but they are computable.
- Unstructured data: This includes data such as natural-language text, video, audio, and images, which lack an organized structure or a defined model and are therefore more complex to manage.
Benefits of a Data Lake: Scalability and Costs
Scalability and cost are two critical aspects of data management, and data lakes effectively address both of these issues.
Scalability refers to a system’s ability to adapt to an increasing workload without sacrificing performance. In practical terms, if your company begins to generate data at a faster rate, a data lake can expand to accommodate the growing volume.
This is made possible by the use of storage architectures such as Hadoop, which distributes data across multiple servers or nodes. Scalability is not limited to data storage alone but also applies to processing operations. Platforms such as Apache Spark offer the ability to perform distributed computations on stored data—a capability not available in other storage systems, which limit access to a small number of processes.
Let’s now talk about total cost of ownership (TCO). TCO isn’t just the initial cost of implementation; it also includes operating and maintenance costs. Thanks to their distributed architecture, data lakes can offer a lower TCO in the long run. Instead of having to invest in expensive hardware or software licenses, you can scale cost-effectively by adding more nodes to the network as needed.
This variable-cost model enables a faster and more flexible return on investment (ROI).
Turn your data into renewable energy with artea.com: Your ideal partner for customized data lake solutions
We often hear that data is the “oil” of the digital age: we side with those who view data more as a renewable energy source. From this perspective, a data lake is no longer a luxury but a necessity. If you’re looking for effective strategies to manage your information assets, artea.com is the right partner for you.
From the automotive and IoT sectors to video surveillance and geolocation for telecommunications, we are able to provide advanced services for the creation and management of data lakes and customize them to meet the specific needs of each client. Whether in the cloud or on-premises, our technological expertise enables us to implement innovative solutions for managing your data.